Next-generation AI network infrastructure

Strengthen compute with the network to buildthe large-model eraa new AIDC infrastructure

HARNETS rebuilds AI cluster networks with the original ZCube fabric and supporting technologies, using less network hardware, more balanced communication, and more efficient tuning and operations to raise effective cluster compute.

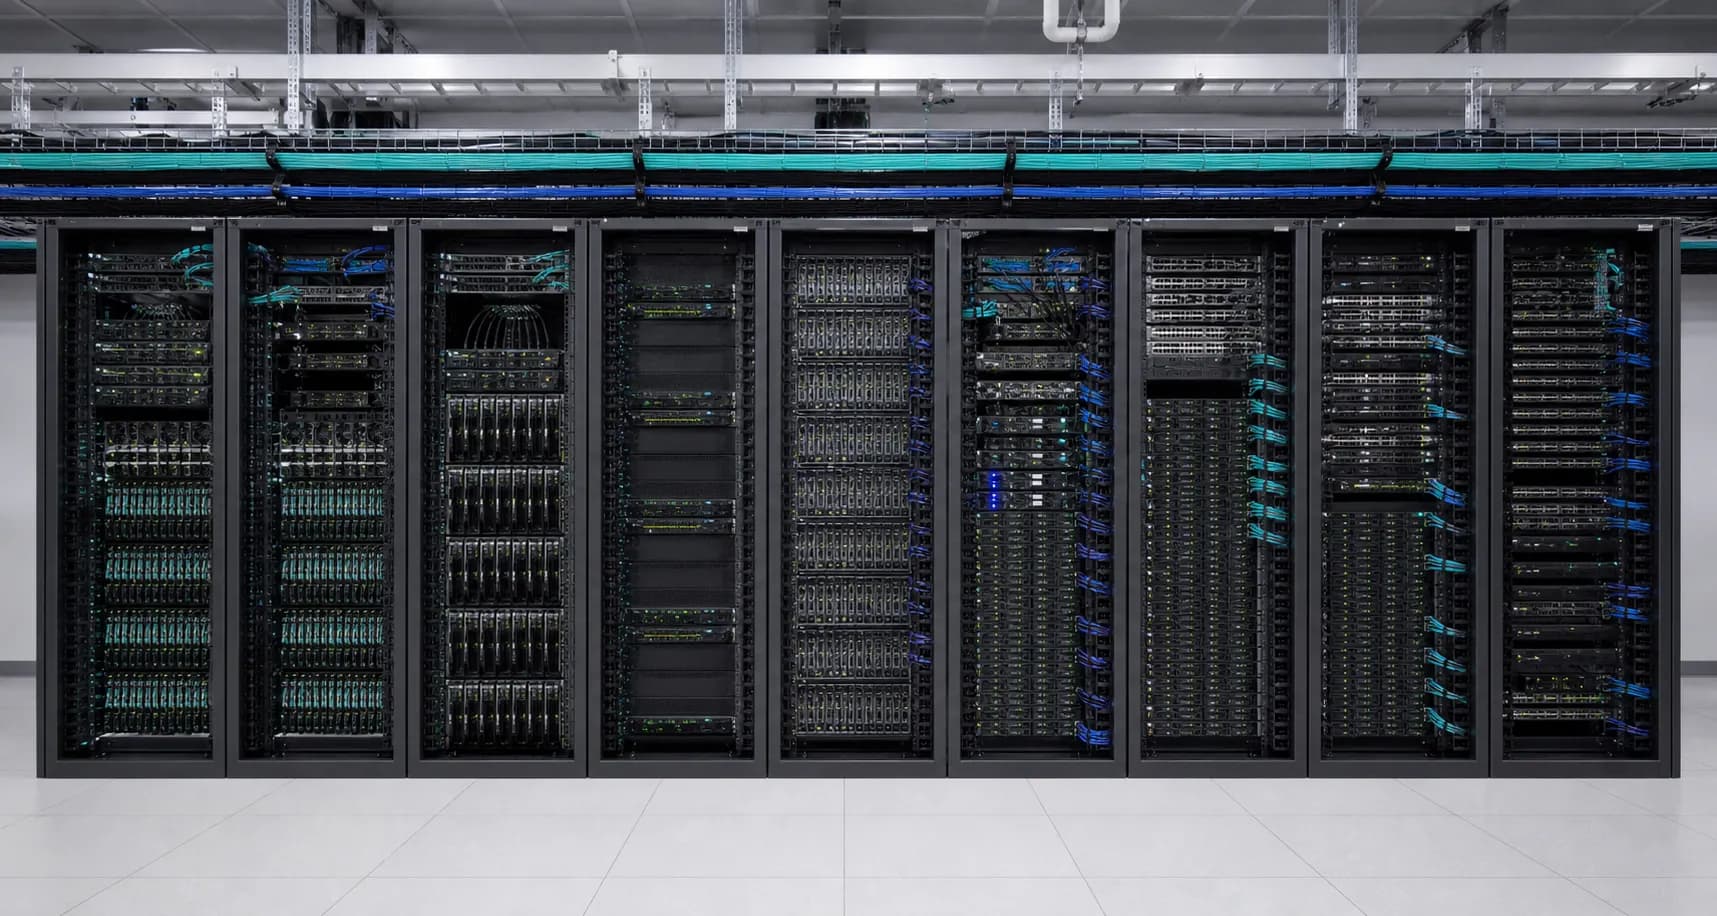
Server racks and network cabling in an AI data center

Network architecture innovation that turns directly into production gains

On a thousand-GPU inference production cluster, GPUs, the software stack, and applications stayed the same; only the network architecture was upgraded from traditional ROFT to ZCube

15%

Average GPU inference throughput increase

More effective compute unlocked by upgrading the network architecture alone.

40.6%

Time to first token (TTFT) P99 reduction

High-concurrency inference tail latency improved significantly.

33%

Network hardware cost reduction

Required switch and optical-module counts dropped sharply.

Focused on customer needs

From cluster build-out to ongoing operations, solving key AI cluster networking problems

For new clusters, existing-network upgrades, performance tuning, and intelligent operations, we combine traffic patterns, hardware, and runtime goals to deliver products and services across the full lifecycle of AI cluster networking.

New AI computing clusters

Large-model companies, AI data centers, and compute operators

Starting from business traffic, we jointly design the network architecture, devices, cabling, and deployment tooling.

Customer value

Build a high-throughput, low-latency AI computing foundation with less network hardware, speed up cluster delivery, and raise effective cluster compute.

Existing-network upgrades

Customers already running Clos / ROFT clusters

Identify hotspots, PFC backpressure, and uneven link load, then upgrade the network architecture without changing business applications.

Customer value

Reduce tail latency and GPU idle time, and raise effective compute on existing clusters.

AI computing performance tuning

Training, inference, and AI infra optimization teams

Profile the full path across training/inference frameworks, communication libraries, network, hosts, and storage to locate throughput and latency bottlenecks.

Customer value

Raise effective large-model training and inference output through cross-layer coordinated tuning.

Intelligent operations

AI cluster operations and delivery teams

Unify compute, network, job metrics, and logs to address scattered monitoring, slow fault localization, and heavy manual troubleshooting.

Customer value

Find anomalies and root causes faster, shorten MTTR, and form a reusable intelligent operations loop.
Products and services

Networking, tuning, and operations in one stack

HARNETS is not a point-device vendor. It is a solution provider built around ZCube and covering the full lifecycle of AI cluster networking.

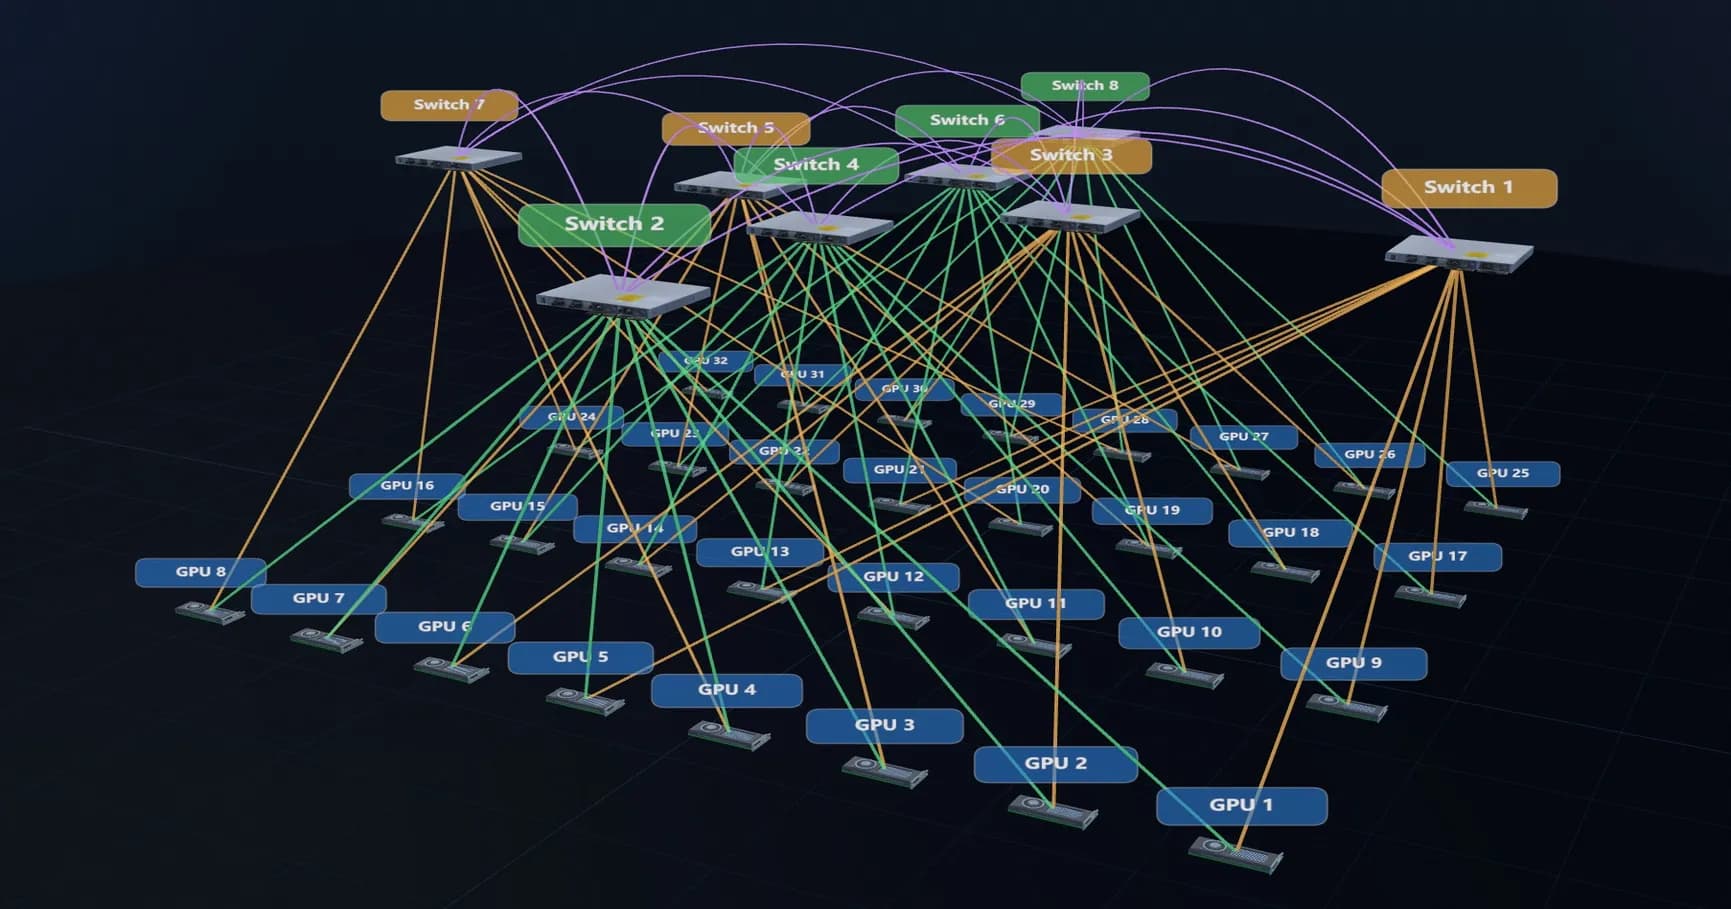
ZCube product visual

AI cluster networking

ZCubeNext-generation AI cluster networking architecture

Replace the traditional multi-tier tree with a fully flat interconnect, remove Spine-layer switches, and combine single-rail plus multi-rail hybrid access with dedicated routing so GPU communication inside the cluster takes shorter, more balanced paths.

Learn about the product
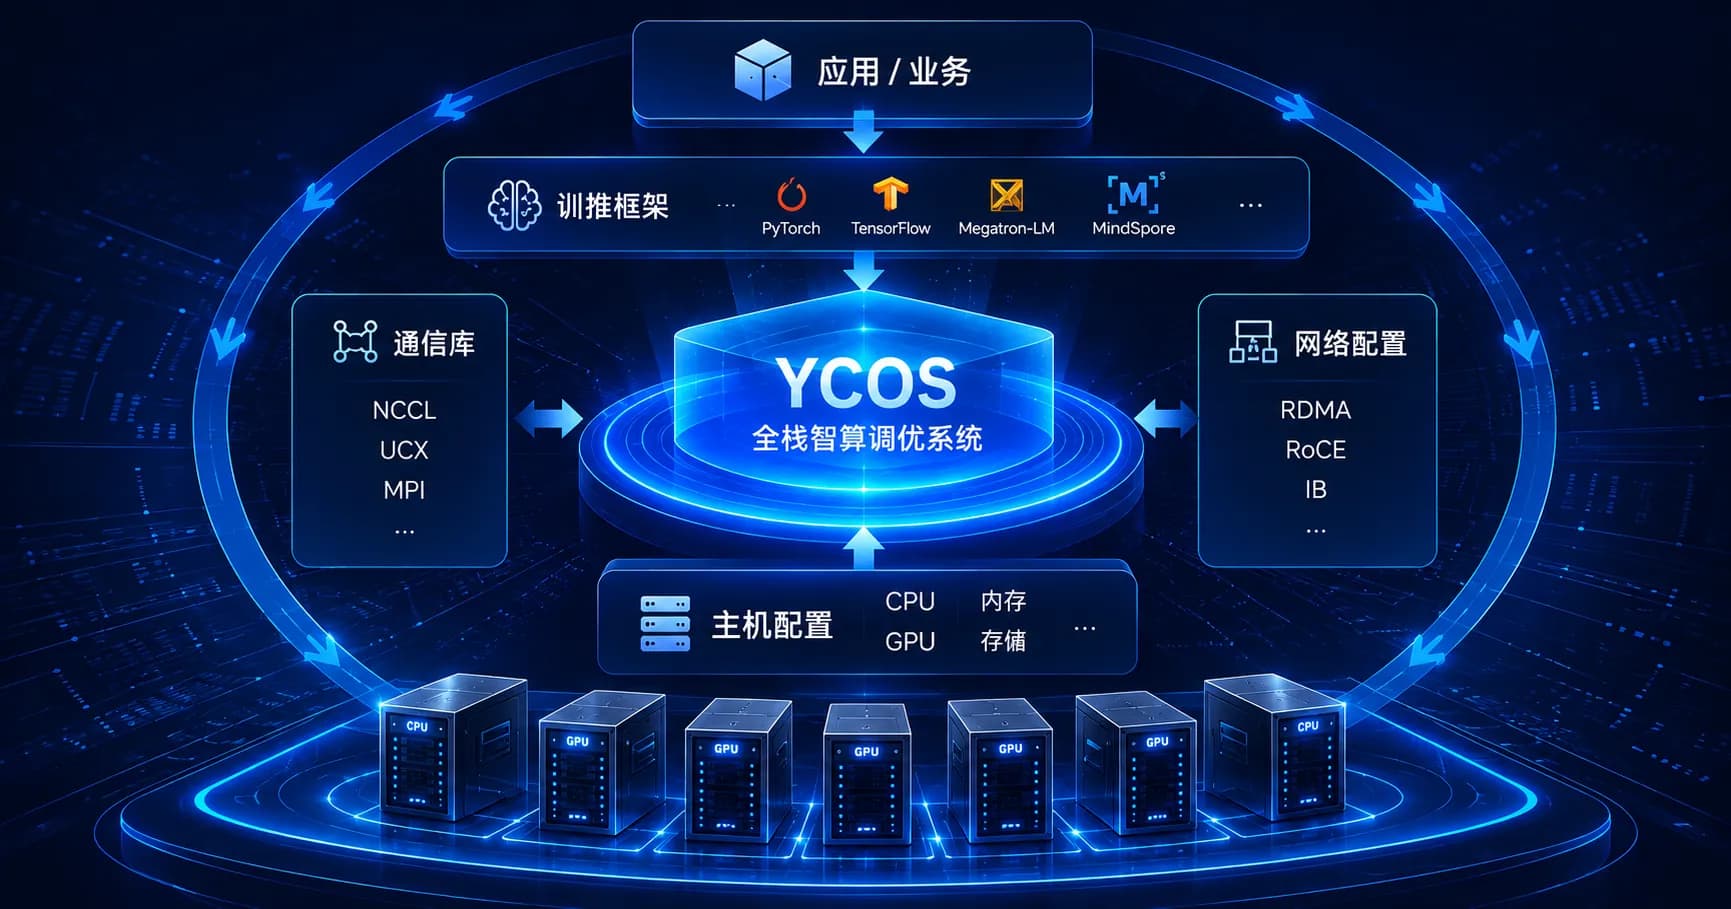
YCOS product visual

AI computing tuning

YCOSAI computing tuning system

For large-scale AI workloads, systematically tune training/inference frameworks, communication libraries, network configuration, and host configuration.

Learn about the product
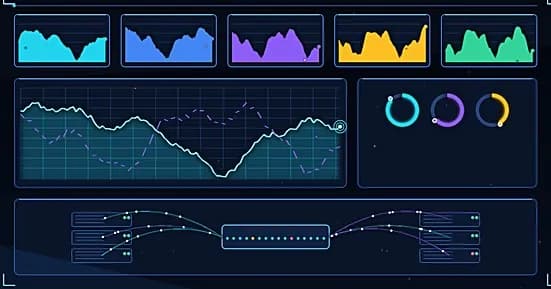
XOPS product visual

AI computing operations

XOPSAI computing operations system

For large-scale training and inference on AI clusters, build an integrated operations platform across compute, network, and storage for faster problem localization and efficient troubleshooting.

Learn about the product
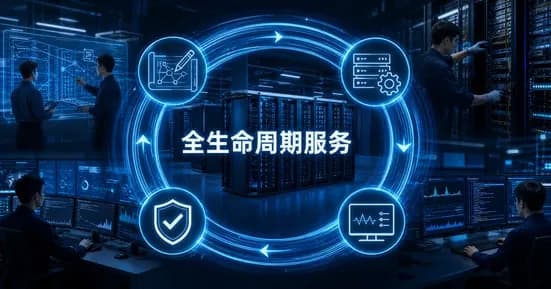
Full Lifecycle Services product visual

Professional services

Full Lifecycle ServicesComplete delivery from planning to go-live

One-stop delivery of network devices, compute-network tuning, and operations services to keep AI cluster networks stable, communication efficient, and SLAs met, helping clusters go live faster.

Learn about the product

Core technology

ZCube: next-generation AI cluster networking architecture

ZCube removes the Spine layer used only for transit, splits Leaf switches into two groups with a complete bipartite interconnect, cutting hop count while improving load balance.

Read the technical blog

Lower networking cost

At the same cluster scale, the number of switches and optical modules is 2/3 of a Clos architecture.

Fewer failure sources

Removing dedicated Spine devices simplifies forwarding nodes.

Shorter communication paths

GPU-to-GPU forwarding across the fabric is only 2 hops, versus 3 to 5 hops in Clos.

Stronger load balancing

Structural global load balancing avoids path-hash collisions and local hotspots.

Smaller failure domains

No Spine-switch failure propagation; a single device failure affects only local nodes.

Better multi-tenant isolation

Link-level traffic isolation reduces interference when multiple jobs run in parallel.

Deployments

Cluster deployments that show ZCube in practice

Open a case study to see the environment, validation or delivery approach, and full results.

Domestic large-model companyThousand-GPU NVIDIA inference clusterProduction delivery

Large-model company NVIDIA thousand-GPU inference production cluster

Using a coding inference service and comparing against traditional ROFT, this case validates that ZCube unlocks more effective inference compute through a flat fabric and more balanced network communication.

15%

Average GPU inference throughput increase

40.6%

Time to first token (TTFT) P99 reduction

33%

Network hardware cost reduction

View case study
Domestic accelerator companyDomestic thousand-GPU clusterProduction delivery

Domestic accelerator company thousand-GPU production cluster

A domestic thousand-GPU cluster has been live and stable for months, continuously carrying real traffic and serving real users.

Thousand-GPU scale

Domestic compute cluster deployed

Months

Stable production operation

Real users

Continuous service

View case study

Industry connections

From a top-tier networking paper to large-scale industry practice

ZCube-related work was published at ACM SIGCOMM 2025 and selected for the 2026 WAIC SAIL Award TOP30 and as an ODCC outstanding project.

  • ACM SIGCOMM 2025, a top-tier networking conference
  • 2026 WAIC SAIL Award TOP30
  • Participating in the AI computing system architecture alliance, building the ecosystem with industry partners
  • Advancing ZCube compute networking architecture standards
About HARNETS

Original architecture

Trade hierarchy for efficiency, and determinism for performance

Authoritative recognition

SIGCOMM 2025 and SAIL TOP30

Industry deployment

Multiple GPU types and multiple thousand-GPU clusters

Engineering capability

Controller, toolchain, and full-lifecycle delivery

Start with the network

Make the next AI data center more efficient, starting with the network

Whether you are building a new cluster, upgrading an existing network, tuning performance, or deploying intelligent operations, we can assess how the network can unlock more effective compute.

Contact us