Full-path metric coverage
Covers GPU compute, host resources, host networks, inter-server networks, and training/inference logs.
For large-scale training and inference on AI clusters, build an integrated operations platform across compute, network, and storage for faster problem localization and efficient troubleshooting.
Product positioning
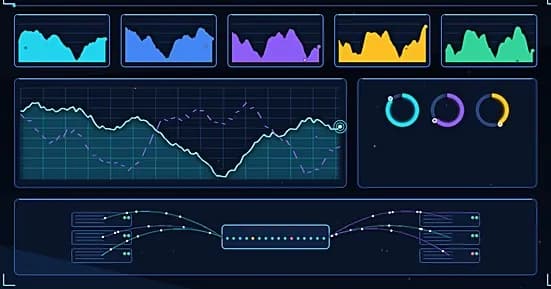
XOPS unifies GPU, host, network, and training/inference job monitoring, then uses visualization and multi-agent collaboration to connect anomaly detection, root-cause localization, ticket analysis, and closed-loop handling.
Core capabilities
Core capability architecture
For large-scale training and inference, metrics, status, and logs are presented together to help locate issues quickly.
Covers GPU compute, host resources, host networks, inter-server networks, and training/inference logs.
Present compute, network, and job metrics together to reduce silos and switching across systems.
Jointly analyze alerts, metrics, logs, and tickets to assist root-cause localization, automatic ticket replies, and closed-loop handling.
Evaluate large models on long-horizon network operations tasks, build an operations experience library and Skills, and recommend the best-performing model.
Value and results
Unified data and intelligent analysis improve completeness of information, response speed, and automation in AI cluster operations.
Break silos among compute, network, and job data with a unified view.
Locate root causes quickly and shorten MTTR.
Agents assist independent diagnosis, automatic ticket replies, and end-to-end closed-loop handling, reducing manual effort.
Products and services
Networking, tuning, operations, and professional services work together to cover the full lifecycle of AI cluster networking.
AI cluster networking
Replace the traditional multi-tier tree with a fully flat interconnect, remove Spine-layer switches, and combine single-rail plus multi-rail hybrid access with dedicated routing so GPU communication inside the cluster takes shorter, more balanced paths.
Learn about the productAI computing tuning
For large-scale AI workloads, systematically tune training/inference frameworks, communication libraries, network configuration, and host configuration.
Learn about the productProfessional services
One-stop delivery of network devices, compute-network tuning, and operations services to keep AI cluster networks stable, communication efficient, and SLAs met, helping clusters go live faster.
Learn about the productWhether you are building a new cluster, upgrading an existing network, tuning performance, or deploying intelligent operations, we can assess how the network can unlock more effective compute.