Research

Explore the frontier of AI cluster networking and unlock more effective compute

Focusing on new AI cluster networking architectures, network performance optimization, and production practice, presenting HARNETS research and validation in AI network infrastructure.

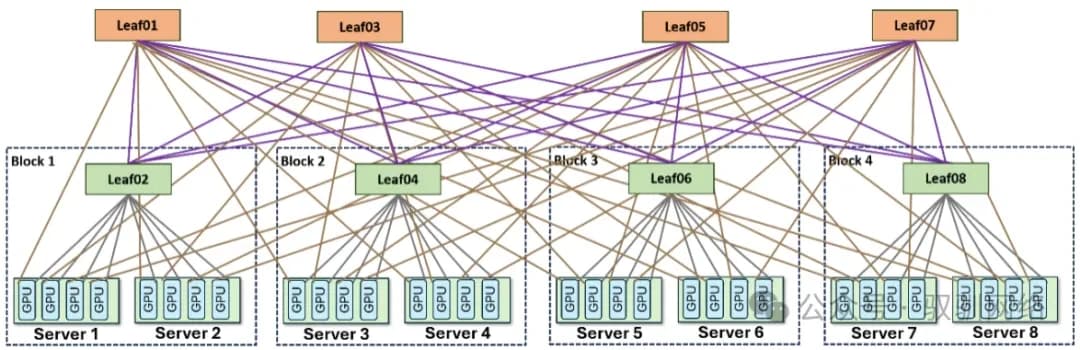
AI cluster networking research equipment and topology

Research articles

Technical blogs on AI cluster networking

6 research articles, sorted by publication date.

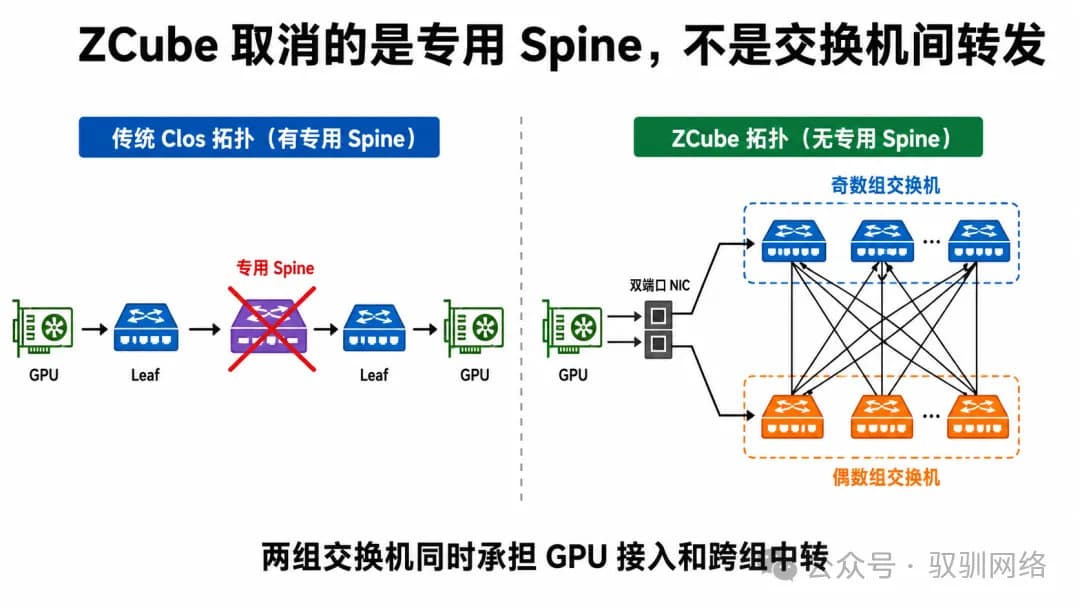
Remove the Spine layer: how does ZCube interconnect thousand-, ten-thousand-, and 100,000-GPU AI clusters?
Research

Remove the Spine layer: how does ZCube interconnect thousand-, ten-thousand-, and 100,000-GPU AI clusters?

From switch radix, GPU downlink count k, and network planes, this article explains how Spine-less ZCube scales to thousands, tens of thousands, and even 100,000 GPUs, and why it is a system design of topology, routing, cabling, and a controller.

Read more
Spine-less ZCube: why is it both cheaper and faster?
Research

Spine-less ZCube: why is it both cheaper and faster?

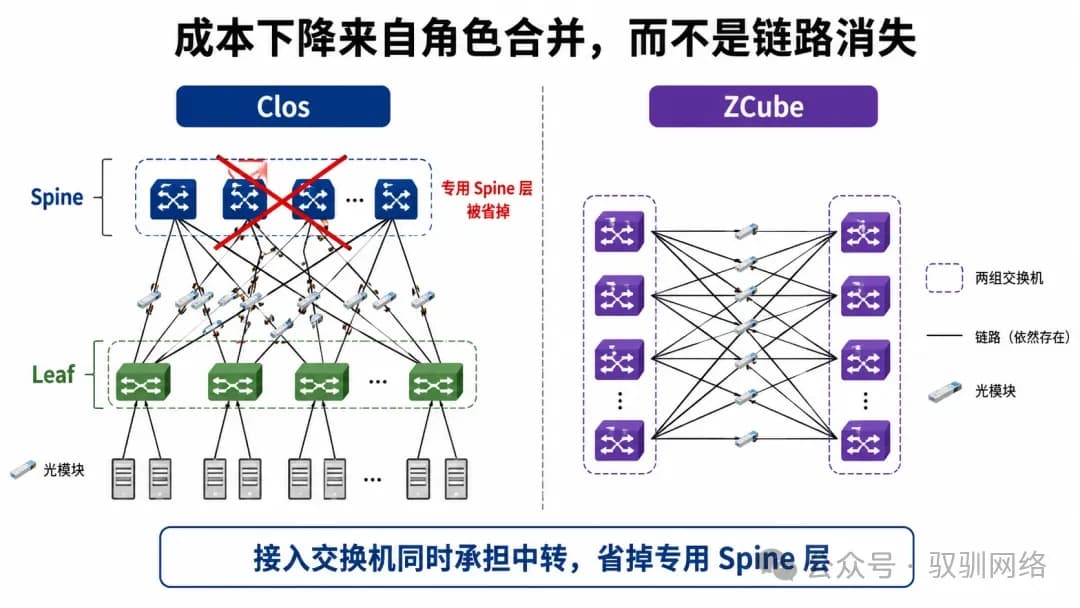
From port budget, hardware cost, path hotspots, automated operations, NCCL adaptation, and fault-tolerance limits, this article analyzes how Spine-less ZCube balances cost reduction and performance.

Read more
ZCube: easing AI traffic path collisions with structured network load balancing
Research

ZCube: easing AI traffic path collisions with structured network load balancing

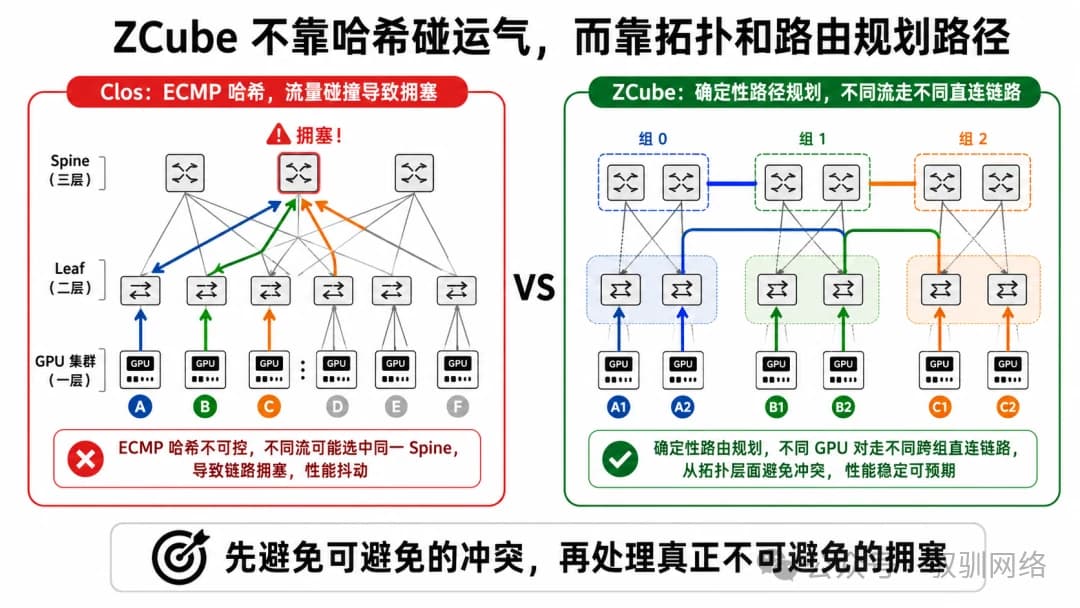
From deterministic GPU-pair paths, ECMP hash collisions, collective communication, and P/D-disaggregated inference, this article explains ZCube structured load balancing and Incast limits.

Read more
Without Spine switches, what does ZCube use to carry the GPU-cluster interconnect?
Research

Without Spine switches, what does ZCube use to carry the GPU-cluster interconnect?

From Scale-Out limits, ROFT constraints, and a complete bipartite graph, this article explains ZCube interconnect logic after dedicated Spine switches are removed.

Read more
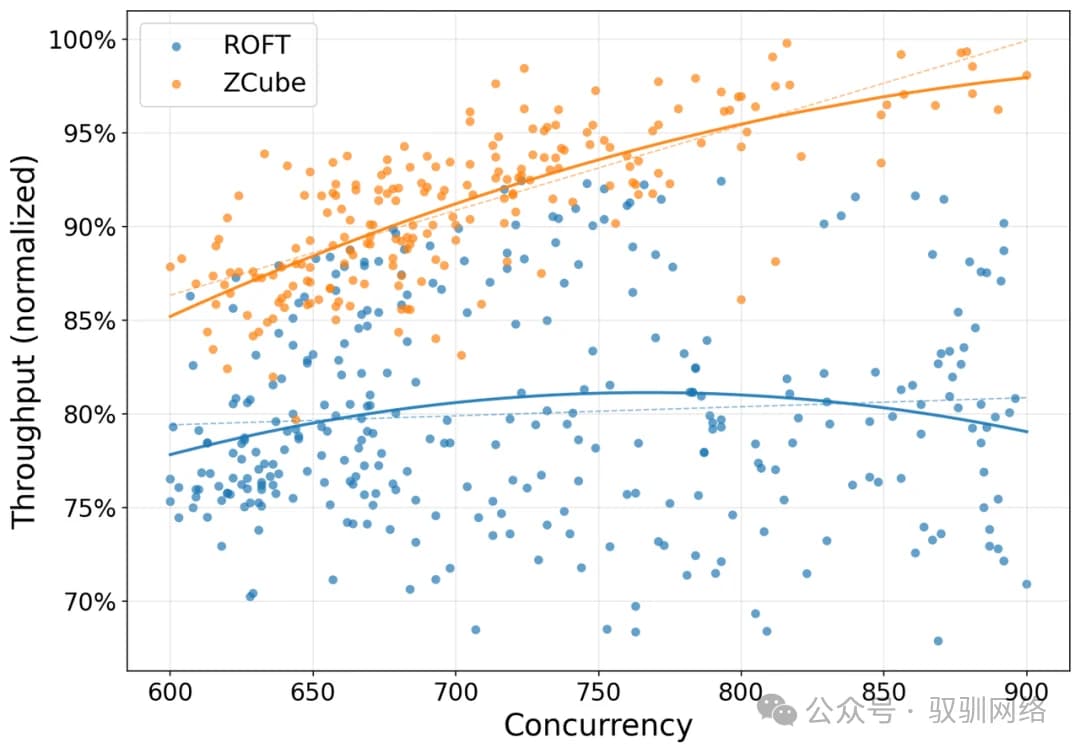
Analysis | How the ZCube architecture improves network performance metrics
Research

Analysis | How the ZCube architecture improves network performance metrics

Using months of production data, this article explains the relationship among PFC RX, KV Cache latency, and inference performance gains.

Read more
HARNETS: next-generation AI network infrastructure for extreme token production efficiency
Research

HARNETS: next-generation AI network infrastructure for extreme token production efficiency

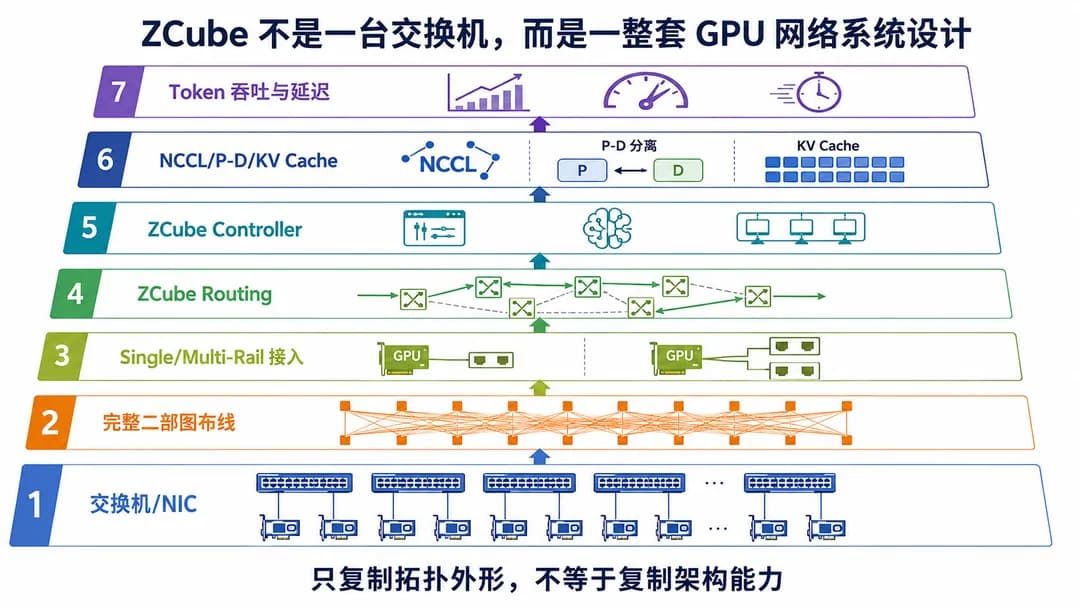
A systematic introduction to ZCube design principles, key technologies, structural advantages, and production deployments.

Read more
Start with the network

Make the next AI data center more efficient, starting with the network

Whether you are building a new cluster, upgrading an existing network, tuning performance, or deploying intelligent operations, we can assess how the network can unlock more effective compute.

Contact us